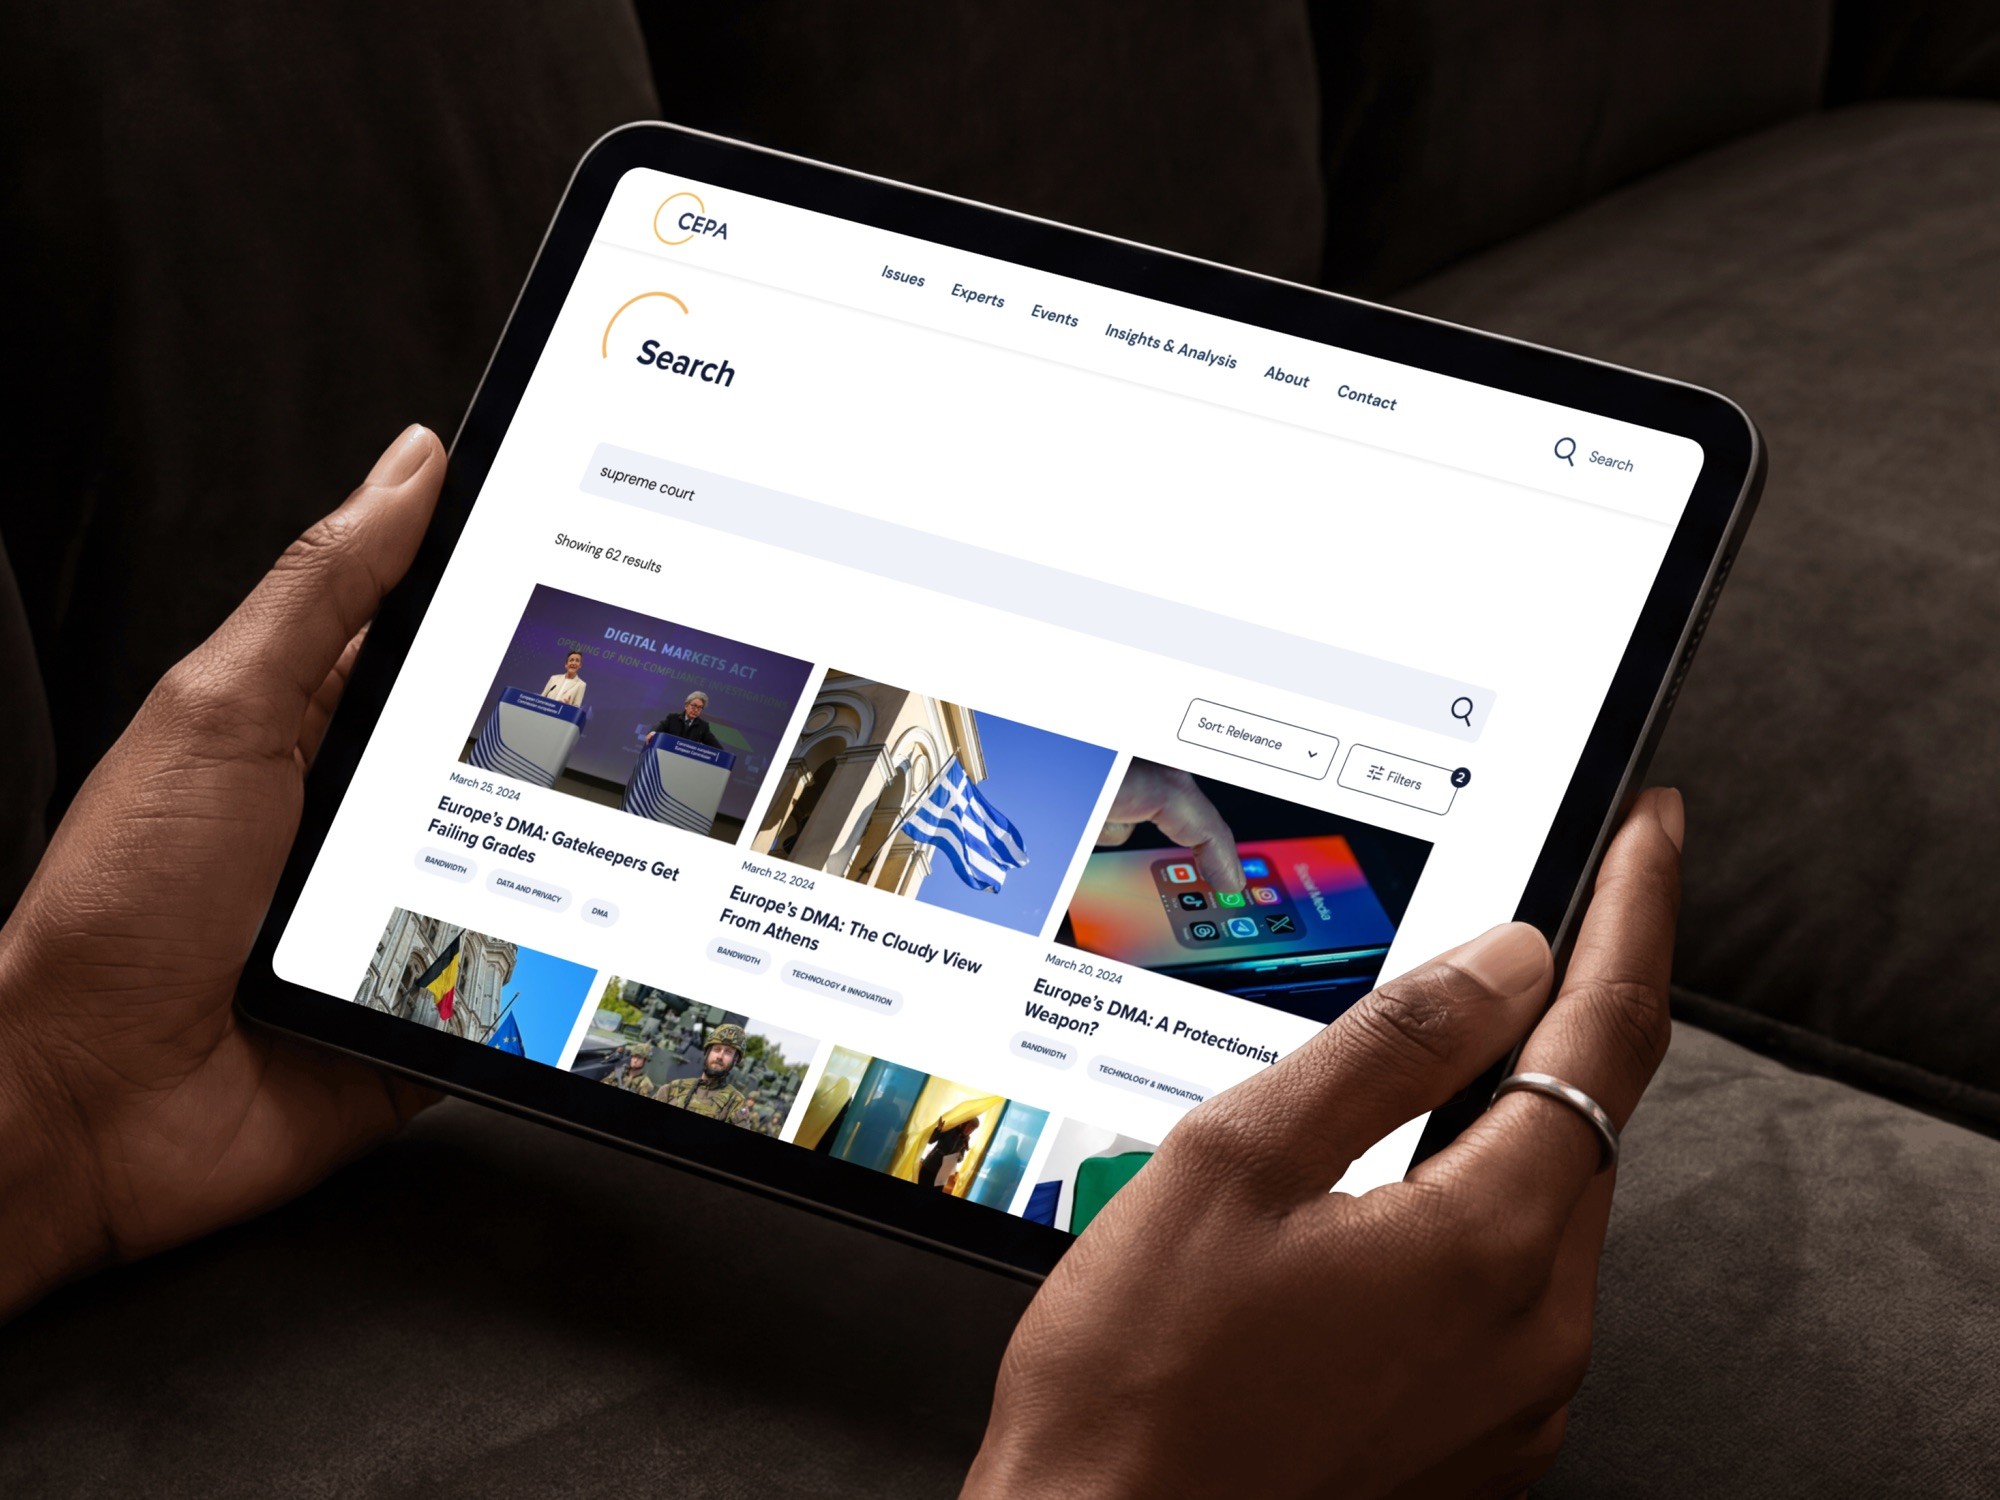
CEPA is a transatlantic foreign-policy institute publishing on NATO, Ukraine and EU tech policy, with years of articles, reports, events and expert profiles, none of it categorised in a way you could search. The job was to audit what was there, work out why tagging kept failing, build a taxonomy across all of it, then design the search on top.
One keyword returned 349 results, with people, events, articles and PDFs run together in a single list. Underneath that, four kinds of content had never shared a tagging system, and staff weren't tagging consistently because tagging was tedious.

I ran the content audit before there was a contract, which framed the proposal that followed. Treated as a staffing problem, inconsistent tagging gets a policy and a training session and stays broken. Treated as a design problem, it gets a shorter, better-ordered vocabulary, which is what it got: one taxonomy across all four content types, nineteen shared issue tags.
Filter order on the resulting search was ranked from what the archive actually holds and from the query logs, rather than from how the institute is organised internally. Internal structure makes sense to everyone who works there and to nobody else, and most readers arrive on a link having never seen the programme names.
Load times fell 70%, the work published, and the relationship has been retained three years and is still running.